An AI agent does not need to become sentient to create a very ordinary business disaster. It can send the same campaign to the wrong list, overwrite clean CRM fields, issue an unauthorized refund, expose a private document, or keep repeating a paid action because nobody set a limit. The failure is usually not science fiction. It is automation moving faster than your controls.
That is why every business deploying agents needs a kill switch and a written response plan before the first incident. In October 2026, NIST published voluntary incident-readiness guidance for frontier superintelligence training and evaluation. Your ten-person company is not training a frontier model, but the practical principles travel well: know who can stop the system, preserve evidence, rehearse containment, and avoid improvising while an autonomous process is still running.
Why “We Can Just Turn It Off” Is Not a Plan
Modern agents rarely live in one browser tab. They may have an API key, a service account, scheduled jobs, access to email and cloud storage, and permission to trigger workflows in other platforms. Pausing the chat interface may not stop a queued campaign or revoke a token. Deleting the original prompt may erase context you need to understand what happened.
A small-business incident plan should answer five questions in plain English: Who owns the decision? Where is the stop control? Which credentials can be revoked? Where are logs stored? Who must be notified? If the answers require a vendor support ticket and three people searching Slack, your response time is already too slow.
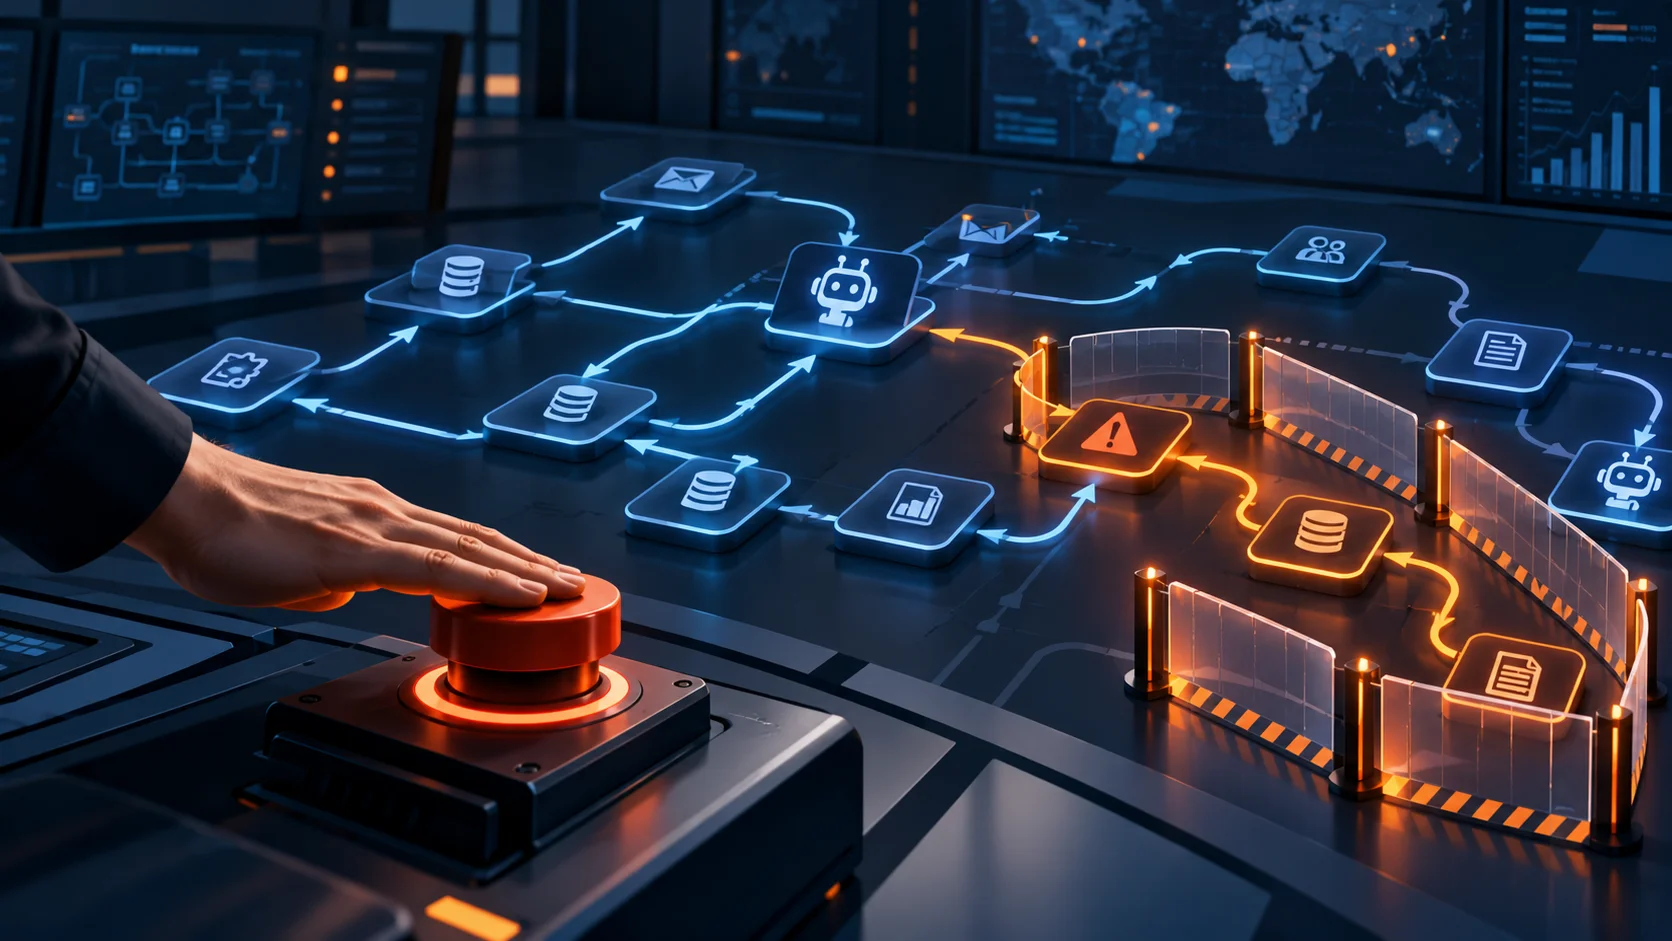
Build the Kill Switch Before You Need It
Give every agent its own identity. Do not run production agents through the owner's personal account. Use a dedicated service account, mailbox, or integration user so you can revoke one agent without locking an employee out of the business. This also makes audit logs readable. Our guide to agent identity and audit trails explains the operating model.
Separate pause, revoke, and contain. Pause stops new work. Revoke removes credentials. Contain blocks downstream systems from accepting actions. You may need all three. An email agent, for example, should have a workflow-level pause, a revocable OAuth connection, and a sending limit at the mail provider.
Set hard ceilings. Put numerical limits around messages sent, records changed, dollars spent, files accessed, and runs per hour. A threshold should stop the workflow and alert a person, not merely add a warning to a dashboard nobody watches. For more on budgets and rate limits, see AI agent cost controls.
Preserve the evidence. Log the initiating user, prompt or task, tool calls, approvals, data read, data changed, timestamps, model or agent version, and final output. Keep logs outside the agent's write permissions. If the agent can alter its own history, you do not have an audit trail.
Define incident severity before emotions take over. A wrong internal draft is not the same as a public customer message, a disclosed payroll file, or a payment sent to the wrong account. Use three levels: low for reversible internal errors, medium for customer-facing or operational disruption, and high for sensitive data, money, legal commitments, safety, or broad public impact. Tie each level to a named decision-maker and notification path.
Keep a manual path alive. If the agent handles intake, reporting, invoicing, or support triage, employees still need a documented way to perform the minimum critical work while it is offline. A kill switch is much easier to use when stopping the agent does not stop the business.
Need a safer agent rollout?
We map permissions, approval gates, limits, logging, and shutdown steps before automation touches live operations.
Book a Free Strategy Call →The First 15 Minutes: Stop, Preserve, Scope
Minute 0–3: stop new actions. Pause the workflow at its orchestrator. Disable schedules and event triggers. If actions continue, revoke the agent's credentials and block its service account. Do not start by editing the prompt; changing instructions while the system is active can create a second unknown state.
Minute 3–7: preserve what happened. Export logs, screenshots, queue contents, recent outputs, and configuration versions. Record who initiated containment and when. Do not delete failed messages or “clean up” incorrect records yet. You need a reliable timeline before repair.
Minute 7–12: scope the blast radius. Identify every connected system and classify actions as read, draft, send, modify, delete, or pay. Check whether downstream automations copied the error. One incorrect CRM field can trigger a customer email, a sales task, and an invoice workflow.
Minute 12–15: assign communication. One person leads technical containment; one owns customer, employee, vendor, legal, or insurer communication. If personal information, payment data, contracts, or regulated records were involved, bring qualified legal and security professionals into the response. This article is an operating checklist, not legal advice.
Recover Without Restarting the Problem
Recovery begins in read-only mode. Reproduce the failure against test data, identify the failed control, and confirm that the fix blocks the same action. Then restore one permission or connector at a time. Watch a small batch, require approval, and compare every result with the expected output.
Do not settle for “the prompt was bad.” Ask why a bad instruction could cause an irreversible action. The durable correction might be narrower permissions, a rate limit, an approval gate, input validation, or a separate tool for high-risk actions. The approval inbox pattern is especially useful when agents can prepare work but a person must authorize sending, publishing, paying, or deleting.
After service is stable, write a one-page review: what happened, impact, detection method, containment time, root cause, corrective controls, owner, and due date. Avoid blame. You want a system that makes the safe action easy and the unsafe action difficult.
Measure two operational numbers after every drill or real incident: time to detect and time to contain. Also record how many records, messages, dollars, or systems were affected before containment. These numbers show whether your controls are improving. A faster model is irrelevant if a failure can still run unnoticed all weekend.
Run a 30-Minute Drill This Week
Choose one live agent and simulate a harmless failure: 50 duplicate drafts, an attempted write to the wrong CRM field, or a request to access a restricted folder. Ask the operator to stop it without advance coaching. Time how long it takes to pause the workflow, revoke access, locate logs, identify affected systems, and name the communication owner.
If any step takes more than five minutes, fix the operating procedure before increasing autonomy. Put the shutdown link, credential owner, vendor contact, log location, and escalation list on one page. Store it where the response team can reach it even if the affected system is unavailable.
Repeat the drill quarterly and whenever you add a connector, expand permissions, change the model, or let the agent execute a new action. Test one uncomfortable scenario each time: the primary operator is unavailable, the vendor dashboard is down, the agent's credential has been copied, or a downstream automation keeps running after the original workflow stops. The drill should expose assumptions while the stakes are low.
The goal is not zero failures. No employee, integration, or AI system earns that promise. The goal is bounded failure: small scope, fast detection, reversible actions, intact evidence, and a practiced human decision-maker. That is what turns an AI agent from an uncontrolled shortcut into a dependable business system.
If you want help designing the controls around your first or next agent, book a free strategy call at apolloagent.ai. We will map the workflow, permissions, approval points, monitoring, and kill switch before you hand over the keys.